Latest posts
-
Optimizing Local Llama 3 Latency for Real-Time Web Applications
Reduce first-token overhead and memory consumption through vLLM parameter tuning and streaming SSE endpoints.
-
Building Deterministic n8n Workflows for Automated Content Ingestion
Construct fault-tolerant execution pipelines that process raw Markdown, validate strict JSON schemas, and update production databases.
-
Bridging ComfyUI Workflows Directly into Headless WordPress Pipelines
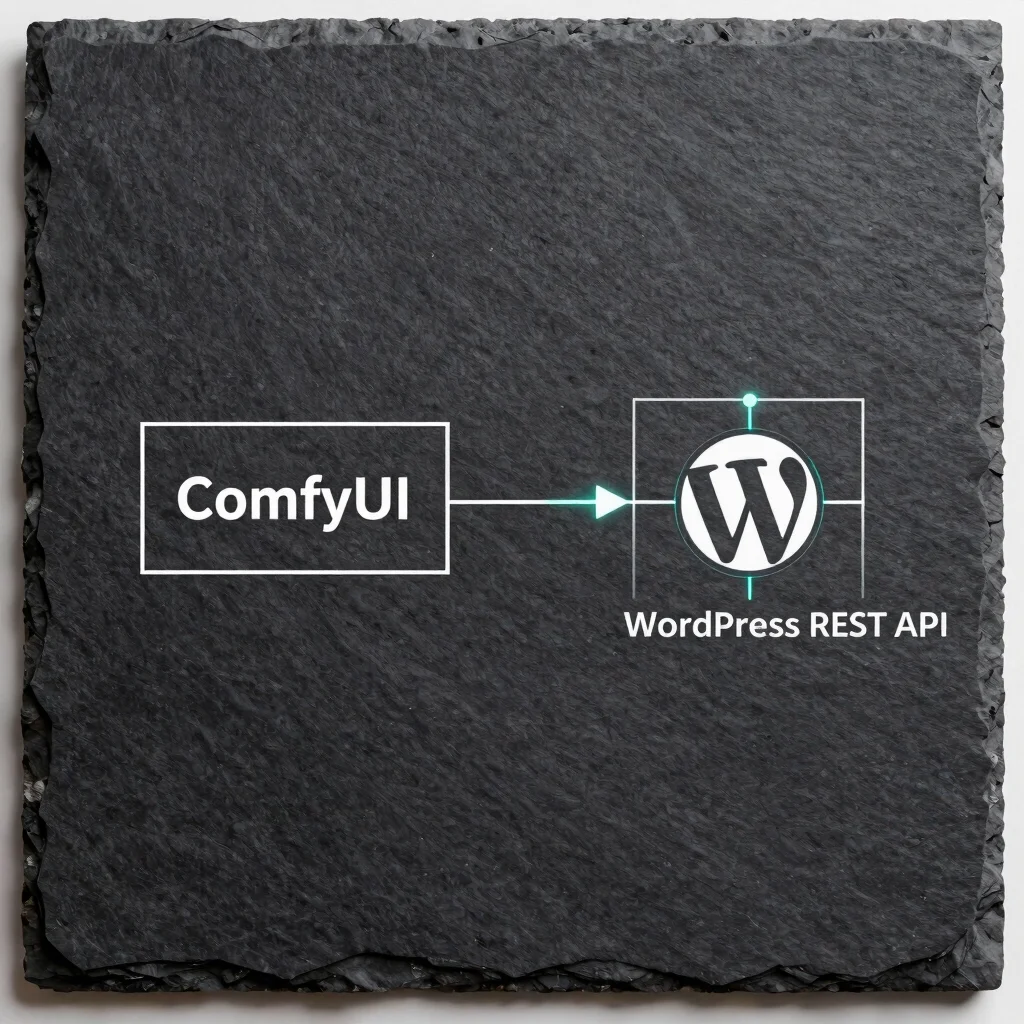
Connect local ComfyUI image generation nodes directly to WordPress REST endpoints with zero manual asset exporting.